The Cheaper AI Gets, the More We Use: A 160-Year-Old Paradox Returns
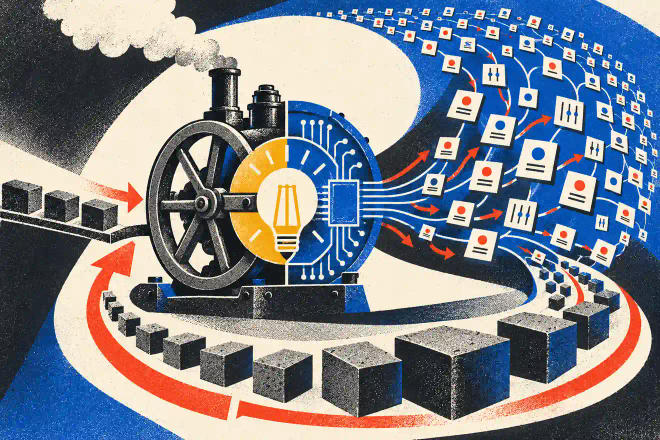
Table of Contents
More efficient steam engines were supposed to save coal. LED bulbs were supposed to save electricity. Today, cheaper AI models promise to reduce computing costs — yet they may produce the exact opposite result. The Jevons paradox explains why.
Imagine a simple situation.
We replace a traditional light bulb with an LED. The new bulb needs a fraction of the electricity to produce the same amount of light. The logical conclusion seems obvious: electricity consumption for lighting must fall.
But then we start using more light. Brighter light. For longer periods. We illuminate the garden, the façade, the stairs, the kitchen worktop, the furniture or a path that was never lit before.
Each individual light is dramatically more efficient, yet we use far more light overall.
Someone noticed a similar effect more than 160 years ago. Not with electricity, but with coal and steam engines.
Today, the same idea is appearing in one of the most interesting places: artificial intelligence.
A new AI model has even been named after it.
When a More Efficient Steam Engine Burns More Coal #
In 1865, British economist William Stanley Jevons published a book titled The Coal Question.
Britain was at the centre of the Industrial Revolution, and coal was one of the foundations of its economy. Steam engines were also steadily improving. They needed less and less coal to perform the same amount of work.
It might therefore seem that technological progress would reduce coal consumption.
Jevons pointed to a problem.
A more efficient steam engine made useful energy from coal economically cheaper. Steam power therefore became worthwhile in more places. More engines and factories were built, and new uses emerged that had previously made no economic sense.
The result could be a situation in which each individual engine consumed less coal while the economy as a whole consumed more.
Today, we know this effect as the Jevons paradox. Jevons published his argument in The Coal Question in 1865.
Its basic mechanism can be reduced to a single chain:
greater efficiency → lower cost → greater use → new use cases → higher total consumption
The final step is the crucial one.
From Coal to LED Bulbs #
Modern economics also uses the term rebound effect.
Suppose a new technology should theoretically cut energy consumption by 50%, but the lower operating cost encourages people to use it more and the actual saving reaches only 40%. Part of the potential saving has “rebounded”.
The Jevons paradox is a more extreme case: additional use absorbs the entire saving or even increases total consumption.
Lighting is a useful example, but it is important to distinguish the short-term behaviour of one household from the long-term development of society as a whole.
A study of German households measured an average direct rebound of around 6% after traditional or halogen bulbs were replaced with CFLs and LEDs. People did use efficient lighting slightly more or choose brighter bulbs, but most of the energy saving remained intact.
When researchers examined lighting over a much longer period, however, the picture became more interesting. An analysis covering roughly three centuries, six continents and five lighting technologies found an approximately 100% historical rebound effect.
Technology enabled us to produce light far more efficiently.
Instead of simply using the same amount of light for a fraction of the energy, we began using light almost everywhere. The authors also stressed that this is not an argument against efficient lighting: people gained far more useful light for a similar share of their income. They summarised the findings in Rebound effects for lighting.
The lesson is that when technology dramatically reduces the price of something useful, human behaviour does not remain unchanged.
Now replace light with intelligence.
What Happens When Intelligence Gets Cheaper? #
Only a few years ago, generative AI was a relatively expensive technology.
If every small operation required a call to a large language model, cost and latency quickly limited the number of places where that approach made sense.
The situation is changing extremely quickly.
Research institute Epoch AI reports that between April 2023 and March 2025, the price per token at an equivalent performance level across the tasks it tracked fell by more than tenfold.
At first glance, that might suggest:
AI will become more efficient, so we will need less computing power.
Reality may be exactly the opposite.
When an AI call becomes cheaper, we will not necessarily make the same number of calls for less money.
We will start making thousands of calls in places where we previously made none.
AI can review every commit. Sort every email. Evaluate every document. Check the output of another model. Decide which model should process a particular request. Monitor logs. Check whether commands are safe. Or generate ten solutions instead of one and ask another model to select the best.
What would be absurd at one dollar per operation may become a routine part of an application at a tenth of a cent.
This is where Jev enters the picture.
The AI Model Named After Jevons #
In September 2026, TypeSafe AI introduced a new model called Jev.
The name is deliberate. It is derived directly from William Stanley Jevons.
TypeSafe AI founder Diogo Almeida previously worked at OpenAI on methods that helped language models follow human instructions more effectively and contributed to the research behind ChatGPT. He explains the choice of name simply: the company expects machine intelligence to follow a path similar to coal in Jevons’ time.
Every order-of-magnitude reduction in the cost of intelligence can unlock orders of magnitude more use cases. TypeSafe makes that connection explicit in its introduction to Jev.
Jev is also interesting from a technical perspective.
It is not another chatbot.
AI That Does Not Want to Write #
A conventional large language model generates text sequentially.
Token by token.
That makes it extraordinarily versatile. The same model can write an email, explain quantum physics, analyse a contract or produce code.
But many decisions inside software do not require any prose.
Imagine an application receiving an email and needing to answer only three questions:
- Is it an invoice?
- Is the message urgent?
- Which department should receive it?
We can ask a traditional LLM to analyse the problem and then generate JSON.
Jev takes a different approach.
It receives the state of the system and a set of precisely defined questions. Instead of free-form text, it returns structured decisions together with probabilities.
invoice: 97%
urgent: 12%
department: accounting 94%
TypeSafe calls this new class of model a System One Model, referring to the concept of fast, intuitive thinking associated with Daniel Kahneman’s work.
Instead of lengthy reasoning, Jev is intended to serve as a fast decision-making layer inside software.
An “Intelligent If” Instead of an AI Chatbot #
This may ultimately be more interesting than another model that can write a slightly better essay.
TypeSafe uses a particularly apt comparison: smart if-statements.
Programming is full of decisions:
if A happened, do B
otherwise, do C
The problem begins when a decision cannot be captured by a simple rule.
Is this comment spam?
Is this order suspicious?
Which employee should receive this request?
Does this user command appear safe?
Should this question be sent to an expensive reasoning model, or will a small, inexpensive model be enough?
This creates room for very cheap decision-making AI embedded deep inside ordinary application logic.
Not one large chatbot on the home page.
Instead, hundreds of small intelligent decisions hidden inside the application, many of which the user will never see.
200 Times Faster? Treat the Numbers Carefully #
TypeSafe reports striking figures for Jev.
According to the company, responses take approximately 70 to 500 milliseconds, and on some tasks Jev can be around 40 to 200 times faster than the large models used for comparison.
In its own workflow evaluations, TypeSafe reports a 193.6-fold speed-up and a 444.6-fold cost reduction. Its published pricing lists input at $0.042 per million tokens, with no separate charge for output.
These numbers need a large asterisk.
They come from the company that built the new model. TypeSafe itself acknowledges that the results probably represent the upper end of what can be expected in real applications, and Jev remains in early access.
Initial tests by independent developers are interesting, but they are not yet a definitive benchmark. TechCrunch describes a Vercel test in which Jev classified command safety five to eighteen times faster, as well as a business email classification test in which Gemini was slightly more accurate but 10 to 20 times more expensive.
There is another important qualification.
The claim that Jev “cannot hallucinate” needs to be interpreted correctly.
Because the allowed output options are defined in advance, Jev cannot invent a nonexistent parameter midway through a response or start writing an essay when the application expects a number.
It can still make the wrong decision.
The difference is that it also supplies an estimate of its confidence. An application may decide to continue automatically at 99% confidence but ask a person or a more capable model when confidence is only 55%.
That is an important distinction when designing real systems.
The Jevons Paradox Built into the Product Name #
This brings the argument full circle.
Jev is not intended to save computing resources by allowing us to use AI just as often while making each call cheaper.
The idea is the opposite.
If one intelligent decision becomes cheap and fast enough, we can place it where nobody today would consider calling a large language model.
For example, the model can decide what a game character should do ten times per second. TypeSafe demonstrated Jev this way in Doom. It can also supervise another AI model, route requests or continuously evaluate thousands of objects within a system.
Suddenly, we do not need one AI call.
We need ten.
Then a thousand.
Then a million.
Cheaper AI may therefore result in far greater total AI consumption.
This is not merely a philosophical possibility. The International Energy Agency reports that electricity consumption by AI-focused data centres rose by approximately 50% in 2025. Its current projection has total data-centre electricity consumption increasing from around 485 TWh in 2025 to 950 TWh in 2030.
The efficiency of each individual computation can therefore increase sharply at the same time as the total number of computations grows.
Just as it did with the steam engine.
What This Could Mean for Application Development #
The most interesting change may not be that chatbots produce better answers.
It may change the way we think about software itself.
Today, development teams often ask:
Does it make sense to add AI to this application?
If intelligent decision-making becomes cheap enough, a few years from now that question may sound as strange as asking today:
Does it make sense for this application to use a database?
AI does not have to be a separate feature behind a large “Ask AI” button.
It can become an ordinary building block of the system.
One model solves a difficult problem. A smaller model checks the result. Another decides where to route the request. A different one estimates risk. The large reasoning model is invoked only when the cheaper model decides that it is genuinely needed.
From a development perspective, the most important question will no longer be simply whether to “use AI”.
What matters more is knowing which kind of intelligence belongs where, how much of it is needed and what should remain ordinary deterministic code.
That is a far more interesting problem.
Jev May Succeed. It May Not. The Paradox Remains. #
Jev is only days old, and it would be premature to claim that this particular model will transform software development.
It may succeed.
Other companies may adopt its ideas.
Or, a few years from now, Jev may be no more than an interesting footnote in the history of AI.
That does not change the underlying principle.
The cost of machine intelligence is falling while the number of situations in which we can use it is growing. The result may not be a world in which AI requires less computing power overall.
We may instead create a world where one AI decision is almost negligibly cheap — and for that very reason, we make billions of them.
In 1865, William Stanley Jevons observed that a more efficient steam engine did not necessarily mean less coal.
More than 160 years later, we may be watching the same idea take a new form.
This time, however, we are not burning coal to obtain mechanical work.
We are buying computing power to obtain intelligence.
Sources and Further Reading #
- William Stanley Jevons: The Coal Question (1865)
- Joachim Schleich, Bradford Mills and Elisabeth Dütschke: A brighter future? Quantifying the rebound effect in energy efficient lighting (2014)
- Harry D. Saunders and Jeffrey Y. Tsao: Rebound effects for lighting (2012)
- TypeSafe AI: Introducing System One Models & Jev (2026)
- TechCrunch: A new kind of AI model from a ChatGPT inventor is thrilling developers (2026)
- Epoch AI: Top 10 Data Insights and Gradient Updates of 2025
- International Energy Agency: Key Questions on Energy and AI — Executive summary (2026)